




Retail planning teams waste days every cycle fixing the same data problems. Missing costs. Wrong hierarchies. Duplicate SKUs.
These errors delay plans and break trust in the entire planning process.
The root cause isn't carelessness. It's that planning systems inherit messy upstream data and have no way to catch or correct it before it spreads.
The Dirty Data Tax: Why Planning Breaks at Scale
Retail planning fails when messy product data slips into planning workflows and no one catches it until it’s too late.
The Mid-Cycle Surprise
Every cycle follows the same pattern. Data gets imported. Plans start moving. Then something breaks. Missing costs. Wrong hierarchies. Duplicate SKUs.
The assortment plan stalls, analysts start cross-checking ERP exports against spreadsheets, and buyers lose confidence in the numbers. By the time the issue is fixed, days are gone and trust is damaged.
Why Planning Is Less Forgiving of Bad Data
This is more than an analytics problem. BI tools can tolerate imperfect data. Planning can’t.
A missing landed cost on a few hundred SKUs can freeze an entire financial plan. A hierarchy misalignment can push inventory into the wrong categories. A duplicate SKU can double-count demand and distort buys. What looks like a small data issue quickly becomes a planning execution failure.
Why Upstream Systems Don’t Catch Data Issues
Your PIM manages attributes, but it doesn’t enforce planning rules like valid plan classes, active hierarchies, or complete seasonal financials. Errors still pass through.
So planners build manual validation steps into every cycle, spending 10–15 hours verifying that the data is safe to use. That’s not strategy. That’s maintenance.
Why the Problem Compounds at Scale
As retailers add sales channels, SKUs, and vendors, the problem doesn't grow linearly, it accelerates. And it's structural, not a matter of teams being sloppy. Three architectural realities are usually behind it.
Architectural silos leave no owner for planning logic. Each upstream system enforces its own local rules and nothing enforces cross-functional planning logic.
- Your PIM validates basic metadata like color and description but ignores planning-specific fields like seasonal markdown schedules and landed costs.
- Your ERP and WMS focus on transactions and warehouse movement, so they miss real-world discrepancies like shrinkage, unrecorded damage, and misplaced stock.
- POS and e-commerce log physical sales, but without continuous sync those discrepancies pile up, creating an "availability reality gap" where system inventory no longer matches what's actually on the floor.
The workaround becomes "Excel shadow IT." When scale outpaces the systems, teams default to manual fixes: planners export raw ERP data into disconnected spreadsheets to run their own validations.
Those workarounds split the source-of-truth across Finance, Merchandising, and Supply Chain, so a single misaligned hierarchy in one spreadsheet can double-count demand or misallocate capital across categories.
Batch processing bakes in stale data. Legacy planning architectures still run on nightly or weekly ETL batch updates.
At scale, even minor lag means planners build forecasts on outdated numbers, and by the time an error surfaces mid-cycle, the dependent calculations across budgets, POs, and replenishment plans are already corrupted.
The Real Cost of Dirty Data
The impact compounds. Cycles stretch by 3–5 days. Buy windows get missed. Margin forecasts drift. A 2% error on a $50M category turns into a $1M mistake.
Stakeholders stop trusting the system and go back to Excel. Planning teams become data wranglers instead of decision-makers.
How to Fix your Planning Data Issues
At scale, manual vigilance doesn’t work. The only sustainable model is continuous detection, recommended fixes, and automated corrections before bad data reaches forecasts, budgets, or allocations.
If your team is still firefighting data issues mid-cycle, the problem is your planning workflow isn’t protecting itself.
The Better Model: Automated Data Integrity in Planning Workflows
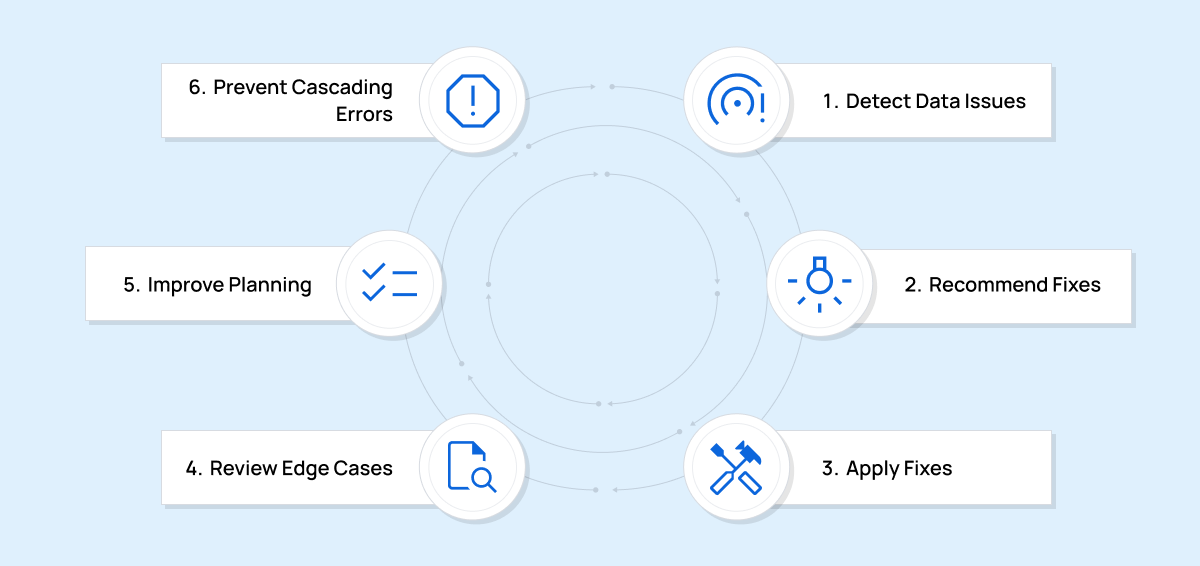
Efficient teams build and work in systems that detect, recommend, and resolve data issues before they affect planning outputs.
Principle 1: Detection should be continuous, not periodic
Every time product data enters or updates, the system checks for inconsistencies, missing attributes, invalid hierarchies, duplicate records. Teams get alerts before the data is used in a plan.
Principle 2: Fixes should be recommended, not discovered
When a SKU is missing a required field, the system suggests a correction based on similar products or historical patterns. The planner doesn't need to research what the value should be.
Principle 3: Corrections should be auditable and reversible
Every automated fix is logged with a reason. If a correction was wrong, it can be undone or overridden without breaking downstream plans.
Principle 4: Governance doesn't mean manual approval for everything
High-confidence fixes apply automatically, correcting a typo, filling a blank field with the standard value. Edge cases get flagged for human review.
Principle 5: Data quality should improve planning velocity, not slow it down
Planners don't spend time validating data. They trust that the system has already done it. Cycle times shrink because data issues are resolved proactively.
Principle 6: Errors shouldn't cascade downstream
If a product attribute is flagged as inconsistent, the system prevents it from being used in forecasts or budgets until it's resolved. Bad data doesn't propagate into reports or decisions.
For Leaders: Structural Fixes Beyond Detection
Detection and recommended fixes solve the day-to-day. But if you're leading planning at scale, three structural moves stop the problem at its source:
- Shift left with strict "data contracts." Enforce entry rules at the ingestion layer instead of cleaning data after it lands. Define schemas that treat planning attributes, like target margin rate, plan class, and vendor lead times, as mandatory, not optional, so incomplete feeds get quarantined before they ever hit an active planning table.
- Use ML for the gaps history can't fill. New product launches have no demand history and often no complete cost data. Attribute-based matching maps a new SKU to comparable historical items using traits like fabric composition and price point, and predictive models can impute a missing landed cost from vendor history, removing the manual lookup entirely.
- Give data a product owner. Routing every fix through a central IT queue creates bottlenecks. A data-mesh approach assigns category managers and planners explicit ownership over their own domain's master data, while keeping every automated fix visible, traceable, and reversible so trust holds across teams.
When Data Slows Planning, Automation Is the Fix
If your planning team spends more time fixing data than making decisions, your data integrity is a planning problem, not a data warehouse problem.
Manual validation doesn't scale. The only way to keep data clean at speed is to automate detection and correction before errors cascade.
The deeper takeaway for leaders: dirty planning data is a structural problem, not simple human error. Scaling well means moving away from reactive spreadsheet fixes toward continuous integrity checks, strict data-entry rules, and domain-owned governance.
Bad product data delays plans and destroys trust in the planning process.
Ready to stop firefighting data issues? Toolio's AI Data Agent automates the detection and correction of product data inconsistencies so your planning cycles run on clean, trusted data from day one. Speak to an Expert to see how it can work for your team!


